HTTP 202 Accepted for Long-Running APIs - Return an Operation, Not a Promise of Success
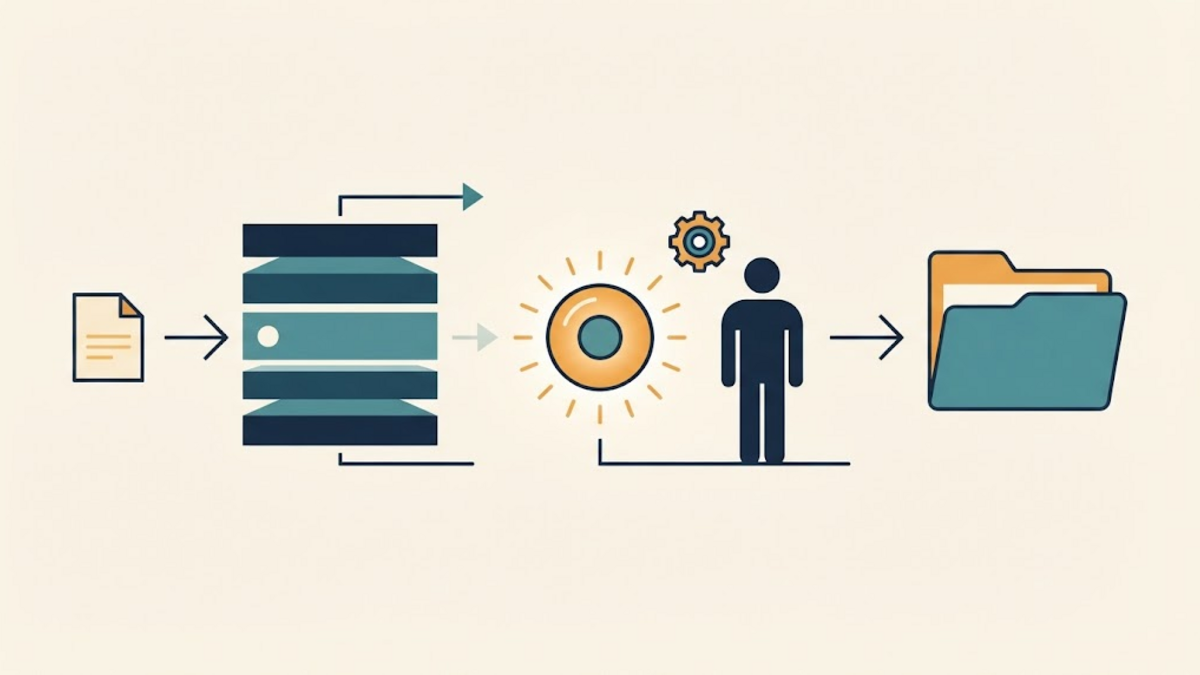
A client asks an API to generate a large report. The work may take several minutes, so keeping one HTTP connection open is fragile. Returning immediately seems sensible, but what can the response honestly say? If it says 200 OK, the report sounds finished. If it says 202 Accepted, the difficult part has only moved: the client still needs to learn whether the work succeeded, failed, or never started.
202 is useful precisely because it makes a narrow promise. It is not a shortcut for “the server will probably handle this.” A dependable asynchronous API needs an observable operation resource around that status code, with explicit states, failure information, access control, and a lifecycle the client can understand.
What 202 actually says
RFC 9110 defines 202 Accepted as a request accepted for processing whose processing has not completed. The work might later be disallowed or might never be acted upon. The response is intentionally noncommittal.
That last word is the important one. A successful 2xx class does not make 202 evidence that the requested business outcome succeeded. It says the server accepted the request into a later process. The RFC also notes that HTTP has no facility to resend a status code from that asynchronous operation. The server cannot retroactively replace the original 202 with 201 Created or 500 Internal Server Error.
The same specification says the response representation ought to describe the request's current status and point to, or embed, a status monitor. That is guidance rather than a universal wire format. HTTP defines the meaning of 202; the API still has to define how clients observe everything that follows.
Separate the request, operation, and result
Three identities are easy to blur:
- The submitted request asks the server to begin work.
- The operation resource represents that particular execution and its changing state.
- The result resource is the report, export, account, or other domain object produced if the operation succeeds.
The operation is not merely an implementation detail. It is the client's durable handle on uncertainty. An illustrative exchange might look like this:
POST /reports HTTP/1.1
Host: api.example.test
Content-Type: application/json

{"from":"2026-10-01","to":"2026-10-31"}

HTTP/1.1 202 Accepted
Location: /operations/op_7f31
Content-Type: application/json

{
  "id": "op_7f31",
  "status": "pending",
  "status_url": "/operations/op_7f31"
}
The field names are application choices, and Location is a common pattern rather than a requirement imposed on every 202 response. What matters is that the contract identifies one stable place where the authorized client can ask what happened.
Make the operation a small state machine
A loose text message such as “still working” becomes difficult to automate. A bounded set of documented states is clearer. A small API might use pending, running, succeeded, failed, and canceled. Other names can work, but clients need to know which states are terminal and which may still change.
{
  "id": "op_7f31",
  "status": "running",
  "created_at": "2026-11-07T00:12:00Z",
  "updated_at": "2026-11-07T00:12:08Z",
  "progress": null,
  "result_url": null,
  "error": null
}
progress should be optional. Some jobs have measurable units; others spend most of their time in one unpredictable step. An invented percentage is worse than no percentage because it turns uncertainty into misleading precision. Timestamps, a current state, and a short description may be enough.
Google's long-running operation guidance uses the same broad separation: an operation has metadata while active and eventually contains either a response or an error. Its exact schema is Google-specific, not a generic HTTP standard, but the distinction is portable. Completion needs a machine-readable outcome, not merely the disappearance of “pending.”
Validate first, then accept durably
Asynchronous processing does not excuse delayed validation. Authentication, authorization, media type, basic syntax, required fields, and inexpensive business preconditions should be checked before returning 202. If the server already knows the request is invalid or forbidden, it should return the appropriate error now instead of creating an operation that is certain to fail.
Acceptance also needs a meaningful durability boundary. If the API returns 202 and then loses an in-memory task during a process restart, the status code described more confidence than the implementation earned. A small application might commit an operation row and queue record in a database before replying. Another system might rely on a durable message broker. The technology is secondary; the response should follow the point at which the application has retained enough information to continue or expose failure.
This does not guarantee the final result. A worker can still fail, a dependency can reject the operation, or an administrator can cancel it. Durable admission only makes the initial promise truthful: the application can account for the accepted operation rather than silently forgetting it.
Polling is a contract, not a tight loop
A client can GET the operation resource until it reaches a terminal state. The API should document a reasonable polling strategy. Without one, many clients will poll as quickly as their loops allow, creating load that does nothing to finish the work sooner.
The Microsoft asynchronous request-reply pattern recommends returning a status location and uses Retry-After as a polling hint. That is useful design guidance, but Retry-After is not a special mandatory component of every 202. Whether it contains a delay, whether clients apply backoff, and whether the estimate changes should be part of the API's documented contract.
Status responses also deserve an explicit cache policy. A shared or browser cache serving an old pending representation can make a completed operation appear stuck. An API can prevent inappropriate storage or define validators and revalidation deliberately. The right policy depends on whether operation data is private, how frequently it changes, and whether caching has a real benefit.
Represent completion without rewriting history
When the report is ready, the operation resource can remain a normal 200 OK representation with status: succeeded and a link to the result:
HTTP/1.1 200 OK
Content-Type: application/json

{
  "id": "op_7f31",
  "status": "succeeded",
  "result_url": "/reports/report_91c2",
  "error": null
}
Another documented design can return 303 See Other from the status endpoint and place the result URI in Location. Microsoft describes that variant because 303 directs the client to retrieve a different resource with GET. It is an option, not the required ending for all asynchronous APIs. Keeping a final operation representation is often helpful when clients need completion metadata or an audit trail.
Failure follows the same principle. The initial 202 remains historically correct: the request was accepted. A later operation representation records that execution failed and provides a stable, bounded error object. The API should distinguish a terminal business or processing failure from a temporary inability to read the status endpoint. Those are different events and may require different client behavior.
Design failure, authorization, and expiry together
An operation URL may reveal customer names, export parameters, error details, or links to generated files. An unguessable identifier is useful, but it is not authorization. Every status, result, and cancellation request must be checked against the caller and tenant that own the operation. Logs should avoid copying sensitive request data merely because the job runs in the background.
Operation records also cannot live forever by accident. The contract should state how long completed operations and generated results remain available, and what clients receive after expiry. AIP-151 explicitly allows operation resources to expire, while Microsoft's pattern also recommends a retention policy. Neither provides a universal duration for a small API. Storage cost, audit needs, privacy, and realistic client recovery windows determine that choice.
Cancellation needs similar restraint. An API may expose DELETE /operations/op_7f31 or another cancellation action, but a cancellation request is not proof that every side effect was reversed. The worker may already have crossed an irreversible boundary. The contract should say whether cancellation is best-effort, which states accept it, and whether partial work requires compensation.
Prefer can express a client preference, not a command
RFC 7240 defines Prefer: respond-async so a client can indicate that it prefers asynchronous handling. It also defines an optional wait preference. A server is allowed to ignore preferences, and the RFC deliberately leaves the mechanism for obtaining the final result implementation-specific.
This header is valuable when an endpoint can choose between a prompt synchronous response and an operation resource. It is not necessary when the API contract always processes that operation asynchronously, and it does not repair an API that lacks status and failure semantics. Preference negotiation and operation design solve different problems.
When 202 is the wrong tool
An operation resource adds writes, polling traffic, cleanup, authorization rules, client states, and monitoring. If the server can complete the request promptly and reliably, an ordinary final response is simpler and more informative. JavaScript being nonblocking does not itself justify server-side 202; a client can await a normal HTTP response without freezing its user interface.
Polling is also not ideal for every workload. Server-Sent Events, WebSockets, webhooks, or a message-oriented interface may fit clients that need low-latency updates or process many results. Those alternatives have their own connection, delivery, and security costs. The decision is not “modern versus old”; it is which observation model both sides can support honestly.
A compact review checklist
- Reject known authentication, authorization, syntax, and validation failures before returning
202. - Persist enough operation state to survive the request process before claiming acceptance.
- Give each operation a stable, authorized status resource.
- Document nonterminal and terminal states, including failure and cancellation.
- Do not invent progress values when progress cannot be measured.
- Define polling guidance, cache behavior, and rate limits.
- Make the eventual result or error machine-readable.
- Define retention, expiry, and behavior after records are removed.
- Test worker crashes, duplicate submissions, lost initial responses, status authorization, terminal failure, and cancellation races.
- Use
202only when separating acceptance from completion is worth the extra protocol state.
Conclusion
202 Accepted is not a promise of success. It is an honest way to say that responsibility has moved beyond the current HTTP exchange. That honesty lasts only if the API gives the client a durable operation identity and a clear route to success, failure, cancellation, or expiry.
For a small API, the design can remain modest: validate first, record the operation durably, return a status link, expose a bounded state machine, and retain the terminal outcome for a documented period. The unanswered question should not be “did the background worker probably run?” It should be a question the operation resource can actually resolve.
References
- R. Fielding, M. Nottingham, and J. Reschke, eds., RFC 9110: HTTP Semantics, Section 15.3.3, June 2022
- James M. Snell, RFC 7240: Prefer Header for HTTP, June 2014
- MDN Web Docs, “202 Accepted,” last modified July 4, 2025
- Microsoft Azure Architecture Center, “Asynchronous Request-Reply Pattern”
- Google API Improvement Proposals, “AIP-151: Long-running operations”