Idempotency Keys for Small PHP APIs - Retry the Operation, Not the Side Effect
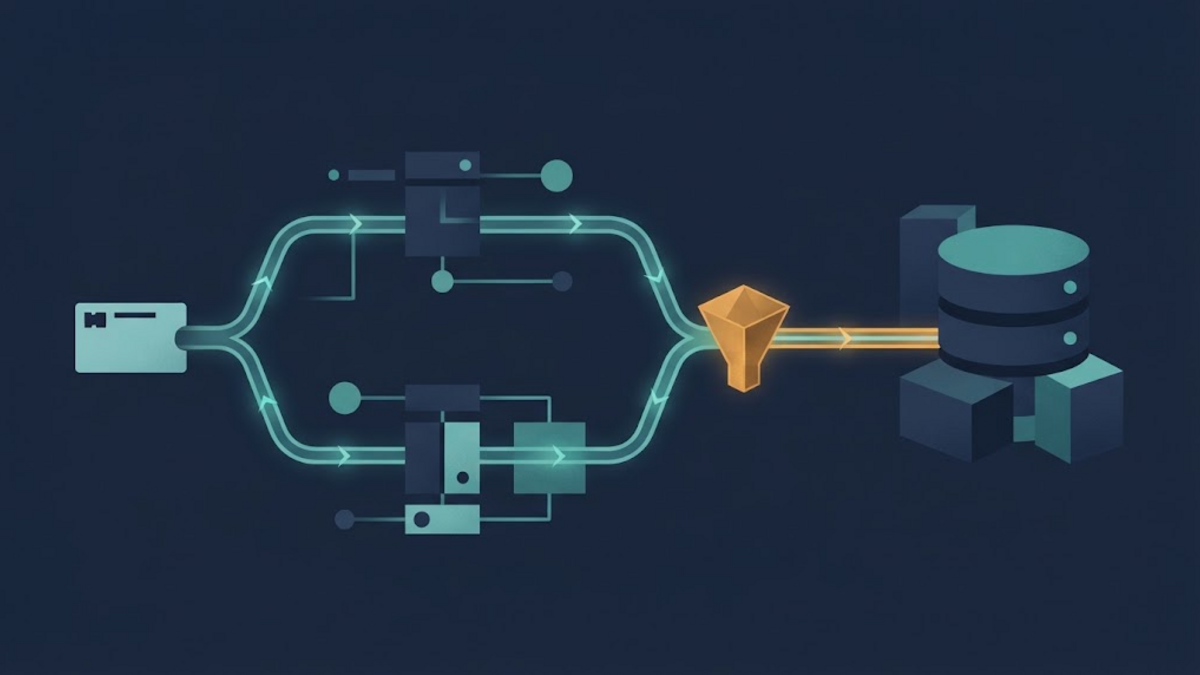
A client sends POST /orders. The server may have committed the order, but the response disappears during a timeout. Should the client retry? If it does, it might create a second order. If it does not, the user may be left with no order at all.
This is not merely a question about retry syntax. It is a question about identity: how can the client say, “this is another attempt at the same operation,” and how can the server remember that decision across concurrent requests and process restarts?
An idempotency key is one answer. It can make an uncertain retry manageable, but the header alone guarantees nothing. The useful guarantee comes from a documented contract, an authoritative store, and an atomic boundary around the key and the business change.
HTTP idempotency and operation idempotency are different layers
RFC 9110 defines an HTTP method as idempotent when multiple identical requests have the same intended effect as one request. PUT and DELETE have idempotent semantics; POST does not receive that general guarantee. This does not mean an idempotent method has no ancillary effects. A server may log every request, and repeated responses do not need to be byte-for-byte identical.
An application can still give a particular POST operation a retry contract. The client creates a unique operation identifier and sends it with every attempt. The server uses that identifier to distinguish a retry from a new intention:
POST /orders HTTP/1.1
Content-Type: application/json
Idempotency-Key: "8e03978e-40d5-43e8-bc93-6894a57f9324"

{"product_id":42,"quantity":1}
The quoted field syntax above follows the current proposal in the IETF HTTPAPI Working Group's Idempotency-Key draft. As of 3 November 2026, that document is draft 08, published on 22 October 2026. It is an active Internet-Draft, not a final RFC. An API can use the pattern today, but it should not present every detail of the draft as settled protocol law.
The API needs a contract, not just a header name
A client cannot safely infer what an unfamiliar server does with Idempotency-Key. The API documentation needs to answer at least these questions:
- Which operations accept or require a key?
- What format and maximum length are valid?
- Within what scope must the key be unique: user, API credential, tenant, endpoint, or something else?
- How long is the result retained?
- What happens when the same key arrives with a different payload?
- What happens while the first attempt is still processing?
- Does a completed retry receive a stored response or a newly constructed equivalent response?
- Which failures may the client retry, and with what delay?
These choices are not universal. Stripe documents parameter comparison, response storage, and pruning behavior for its APIs. Adyen documents account scope, a retention interval, regional limitations, and transient-error behavior. Their policies demonstrate deployed designs; they are not defaults that every small PHP API should copy.
A small state machine makes the behavior visible
It helps to model one scoped key as having three relevant states:
- Absent: no matching operation has been claimed. One request may claim it and begin work.
- Processing: an attempt owns the key, but no final result is available. A concurrent duplicate must not start the business operation again.
- Completed: the operation has a recorded outcome. A later retry receives the stored or semantically equivalent outcome without repeating the work.
There is also an invalid transition: the key exists, but the new request describes different work. That is not a retry. It is conflicting intent and should be rejected clearly.
A conceptual table might contain a tenant or principal identifier, endpoint or operation name, key, request fingerprint, state, response metadata, timestamps, and an expiry time. The important database rule is a unique constraint over the chosen scope and key. A “check, then insert” sequence in PHP is not enough: two workers can both observe absence before either inserts. The database must decide which request wins.
The key and the business write need one atomic boundary
The most dangerous gaps appear when the application records only half of the truth:
- If it records “completed” before creating the order, a crash can suppress an operation that never happened.
- If it creates the order before recording the key, a crash can let a retry create another order.
When the idempotency record and the business record live in the same relational database, one transaction can claim the key, write the order, and record the outcome as one commit. The unique constraint resolves concurrent claims. This is the narrow case where a local transaction gives a clean boundary.
That boundary does not magically include an email service, a payment provider, or another database. A MariaDB rollback cannot undo an external charge that already succeeded. Such workflows need an additional design: the downstream provider's own idempotency feature, a transactional outbox, a resumable state machine, or reconciliation against a stable external operation ID. Calling the outer endpoint “idempotent” must not hide those remaining failure windows.
AWS's account of idempotent API design makes a related point: recording the request token and the mutating work must satisfy an all-or-nothing boundary. It also explains why a caller-provided identifier is often clearer than guessing from equal parameters. Two requests with the same fields may be two deliberate orders, not one duplicated order.
Use a fingerprint to detect changed intent
The client key expresses identity. A server-derived fingerprint checks consistency. For example, the server might canonicalize the method, route, authenticated principal, and relevant validated fields, then store a digest. A later request with the same scoped key must match that fingerprint.
Fingerprint construction is application-specific. Hashing raw JSON bytes is simple, but insignificant whitespace or object-member ordering can make equivalent documents look different. Hashing selected validated values avoids that problem, but the selected fields must include everything that changes the intended operation. The comparison also must happen after the API has established the authenticated scope; otherwise one user's key could collide with or expose another user's result.
The current IETF draft suggests rejecting reuse with a different payload and discusses 422 Unprocessable Content. It suggests 409 Conflict when the original request is still outstanding. Those are useful draft recommendations, not permission to omit API-specific documentation.
Decide what a completed retry returns
One implementation can store the first status, selected headers, and response body. Another can store the created resource ID and reconstruct a semantically equivalent response. Both approaches have tradeoffs.
Exact response storage gives a predictable replay, including a previous failure if that is the documented policy. It also consumes space and can preserve stale or sensitive response data. Reconstruction stores less, but the representation may change after the resource changes or is deleted. The correct promise is therefore not automatically “the same bytes.” It may be “the same operation is not performed again, and the retry receives an outcome consistent with the original intent.”
Retention determines how long even that promise lasts. After expiry, the server may no longer recognize the key. The window should cover plausible retries and delayed requests while respecting storage, privacy, and domain constraints. It should be stated explicitly rather than inherited from a vendor example.
Idempotency is not a complete retry policy or security boundary
A client still needs conservative retry rules. It should reuse the same key only for the same intended operation, apply time limits, respect server guidance such as Retry-After where relevant, and use backoff rather than creating a retry storm. A new key means a new operation.
The server should validate key syntax and length before storage, rate-limit abusive clients, and scope lookups to the authenticated principal. Keys should be high-entropy opaque values rather than email addresses or other personal data. An idempotency key is not authentication, authorization, CSRF protection, input validation, or a substitute for a database transaction.
Observability matters too. Logs can include a safely handled key hash, operation state, resource ID, attempt count, and conflict reason. Metrics for payload mismatches, concurrent duplicates, expired-key reuse, and long-running processing states can reveal client bugs and stuck operations without treating every retry as an error.
When a different design is simpler
Not every POST deserves an idempotency store. A naturally unique business identifier may already prevent duplicates. A client-selected resource URI with PUT may express replacement semantics more directly. A read-only operation does not need this machinery. For a low-impact action where duplicates are harmless, the state, retention, and cleanup cost may exceed the benefit.
The pattern earns its complexity when the outcome can become ambiguous and repeating the side effect is costly: creating an order, scheduling a job, provisioning a resource, or initiating an external action. Even then, the implementation should promise only what it can enforce within a named scope and retention window.
A practical review checklist
- Define one intended operation and the authenticated scope of its key.
- Validate a bounded, opaque key format and reject changed payloads.
- Enforce key uniqueness in the authoritative database, not only in PHP.
- Keep the key claim and local business mutation in one transaction when possible.
- Design explicitly for concurrent duplicates, crashes, and external side effects.
- Document completed-response behavior, retryable errors, retention, and expiry.
- Test a lost response, two simultaneous requests, a changed payload, a process crash, and a retry after expiry.
- Monitor stuck processing states and reconcile outcomes that cross system boundaries.
Conclusion
An idempotency key does not make delivery exactly once. It gives the client a way to name one intention and gives the server a way to recognize another attempt. The actual safety comes from how that name is scoped, claimed, compared, retained, and connected to the business write.
For a small PHP API, the most useful starting point is modest: a clear contract, a database-enforced unique key, a request fingerprint, an explicit state machine, and one transaction for local effects. As soon as the operation crosses into another system, the remaining uncertainty should be exposed and managed rather than hidden behind a reassuring header.