Rate Limiting for a Small Web Application — Slow Down Repeated Failures Without Locking Out Real Users
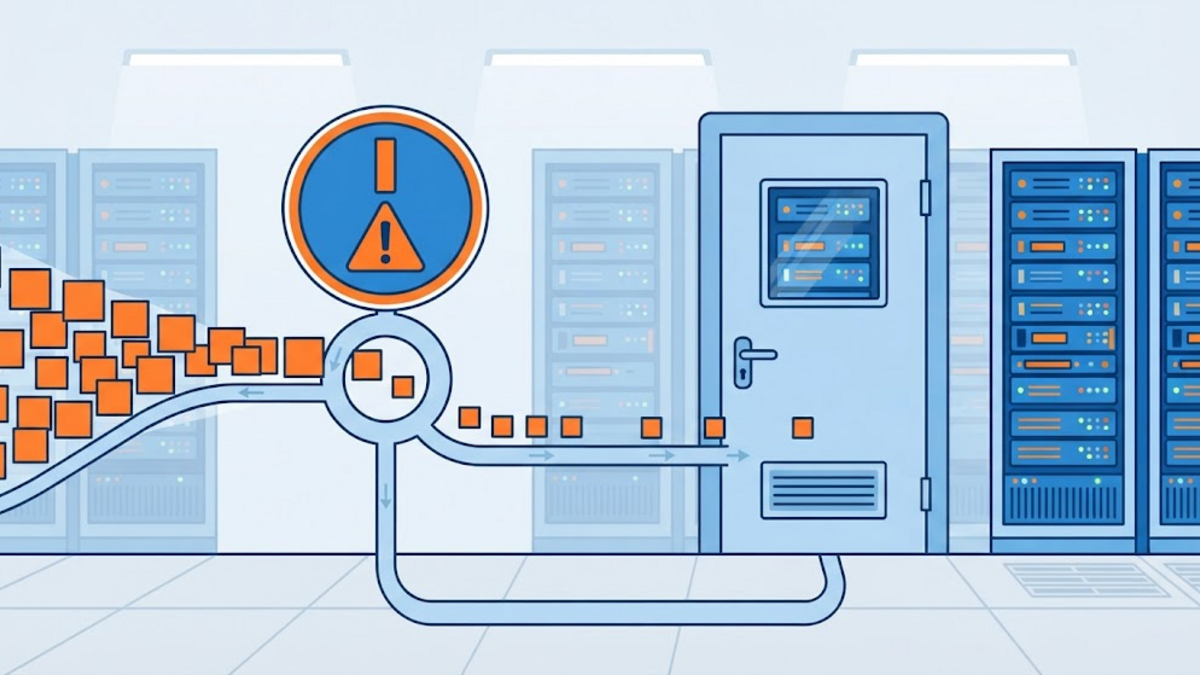
Somebody is going to try to sign in to your application with the wrong password thousands of times. If your login form is on the open internet, that is not a hypothetical; it is what an unattended endpoint eventually attracts. The question is not whether you should push back, but how. The easy answers each break something: blocking an IP forever punishes a shared connection, locking an account after three tries turns your password reset into a weapon, and ignoring it leaves your PHP workers answering a script that will never log in.
This is rate limiting for a small application: the HTTP contract that already exists, the choice of what to count, the two places you can enforce it, and the mistakes that make a limiter worse than no limiter. I wrote it with the stack this site actually runs on — Nginx in front of PHP-FPM over a Unix socket, with MariaDB behind it — and every command and configuration snippet below was checked against that machine rather than recalled from memory. Where a value depends on your traffic instead of on a rule, I say so instead of inventing a number.
What HTTP already tells you
There is a status code for this, and it is old enough to be boring. RFC 6585 defines 429 Too Many Requests for the case where a client has sent too many requests in a given amount of time. The response SHOULD include details explaining the condition, and it MAY include a Retry-After header saying how long to wait. The code is registered in the IANA HTTP status code registry with RFC 6585 as its reference, so it is not a vendor invention clients have never heard of.
The field itself is defined in RFC 9110, section 10.2.3: its value is either an HTTP-date or a number of seconds, and the same field is used with 503 Service Unavailable to say how long a service is expected to be unavailable. That is the whole contract — 429 plus Retry-After — and a client that understands HTTP can obey it without knowing anything about your application.
Two details in RFC 6585 deserve a second read. The specification says explicitly that it does not define how the origin server identifies the user, nor how it counts requests: per-resource, per-server, or across a set of servers, keyed by credentials or by a stateful cookie are all left open. Everything interesting here happens inside that gap. The second detail is less comfortable: responses with status 429 must not be stored by a cache, and the security considerations note that when a server is under attack, answering every request with 429 consumes resources too. The RFC says plainly that servers are not required to use 429 at all, and that dropping connections may be more appropriate. A limiter that spends more CPU than the attack does is a second workload, not a limiter.
Choose the key before you choose the number
Before any rate can be picked, you must decide what is counted: the client address, the account being targeted, or the session presented.
IP-based counting is easiest to deploy and easiest to get wrong. It punishes everyone behind a shared address — a campus network, a mobile carrier's NAT, an office — for the behaviour of one client. It also fails open in the direction that matters most: the OWASP Credential Stuffing Prevention Cheat Sheet notes that credential-stuffing toolkits commonly use proxy networks to spread requests across many addresses, which defeats both IP block-lists and rate limiting, because per-IP request volume stays low even during a high-volume attack.
Account-based counting closes that hole. The OWASP Authentication Cheat Sheet puts it directly: the counter of failed logins should be associated with the account itself rather than the source IP address, so an attacker cannot evade it by moving between addresses. The same document warns about the obvious counter-attack: when you design a lockout, care must be taken to prevent it from being used as a denial of service by locking out other users' accounts. An attacker who knows your endpoint is account-scoped can lock a known customer out on purpose. OWASP lists what has to be balanced: the number of failed attempts before the lockout, the observation window, the lockout duration, and whether that duration grows exponentially with each failure.
That is why the sensible shape is two limits, not one: a coarse limit at the edge keyed by address protects your server's resources from bulk traffic, while a finer limit inside the application keyed by the account protects one account from being guessed. Neither key is sufficient alone, and the two live in different places with different costs when they fire.
Put the limit where the request is cheapest to reject
Rejecting a request before it reaches PHP is much cheaper than accepting it, running a query, hashing a password, and then answering 429 anyway. Nginx can do that with the ngx_http_limit_req_module, which limits the request processing rate per key using a leaky bucket and keeps its state in a shared memory zone.
http {
    limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;

    server {
        location = /login {
            limit_req zone=login burst=3 nodelay;
            limit_req_status 429;
            limit_req_log_level warn;
            limit_req_dry_run on;
        }
    }
}
Several details there are less obvious than they look. The default status for a rejected request is 503, not 429, so limit_req_status 429 is what turns the module's rejection into something a client can read as "slow down" rather than "the site is broken". A rate below one request per second is written per minute, so rate=5r/m is five per minute; burst=3 lets a short spike through, and nodelay accepts those burst requests immediately instead of holding them. limit_req_dry_run on, which arrived in Nginx 1.17.1, counts exactly as it normally would while refusing to reject anything — the honest way to learn whether a threshold fits your traffic before it starts turning away readers. The module also exposes $limit_req_status with values such as PASSED, DELAYED, and REJECTED.
State is not unlimited. The documentation says a stored state occupies 128 bytes on 64-bit platforms, so one megabyte of zone holds roughly eight thousand states; the least recently used state is discarded when the zone fills up, and if a new state cannot be created at all, the request is terminated with an error. That last case matters: a full zone does not degrade gracefully, it fails requests.
The proxy problem that silently merges every visitor
Here is the mistake I would have made myself if I had not checked. $binary_remote_addr is the address of the peer that opened the connection — correct for a directly exposed server, wrong for anything behind a proxy or a tunnel. This site is reached through a Cloudflare tunnel that terminates TLS upstream and talks to the origin over plain HTTP from localhost. I sent one request to the public URL with a unique path, then read the origin's access log:
curl -s -o /dev/null -w '%{http_code}\n' "https://adammuiz.com/__rl_probe_1792602801617611643"
sudo grep __rl_probe /var/log/nginx/access.log
The log records that request as coming from 127.0.0.1. Every visitor on the internet arrives at that Nginx as the same address. A limiter keyed on $binary_remote_addr would put the entire readership into one bucket, and the first few readers to arrive would lock out everyone after them — a self-inflicted denial of service that looks exactly like an attack in the log.
The fix is to tell Nginx which peers may speak for the client, and which header to believe. Nginx does this with the ngx_http_realip_module, which is not enabled by default:
set_real_ip_from 127.0.0.1;
real_ip_header CF-Connecting-IP;
set_real_ip_from declares which peers are trusted to supply a replacement address, and real_ip_header names the header field to read. For traffic proxied by Cloudflare, Cloudflare's own documentation gives exactly this Nginx configuration and points to the published list of Cloudflare addresses in Cloudflare IP addresses for set_real_ip_from, because that list changes and has to be refreshed. Cloudflare's HTTP headers reference adds that CF-Connecting-IP is only sent on the hop from Cloudflare's edge to the origin.
The same trap exists in PHP: $_SERVER['REMOTE_ADDR'] is the peer address too, so an application-level limiter has to use the restored client address, not the socket address. The principle is the one I described earlier about client IPs behind a reverse proxy: trust the connection before you trust the header, and trust the header only when the connection itself came from someone you already trust.
Counting inside the application
The edge limiter protects the server. It cannot tell you that one particular account has failed twelve times, because it does not know which account is being attempted. That check belongs in the application, where the key can be the account rather than the address.
Counting has a small family of models. A fixed window counts hits inside aligned intervals — the first minute of the window, the second minute, and so on. It is simple and cheap, with one predictable weakness: because the windows are aligned, a client can send the full allowance at the end of one window and again at the start of the next. A sliding window counts the hits of the last N seconds regardless of where the boundaries fall, removing that boundary burst at the cost of more history. A token bucket refills a budget over time and lets a client spend it faster when it has accumulated credit — what Nginx calls a leaky bucket. For a login endpoint on a small server a fixed window is usually enough, provided you know the boundary is there.
Here is a fixed-window counter in PHP on top of MariaDB, using an upsert so the increment and the read happen against the same row:
<?php
final class FixedWindowLimiter
{
    public function __construct(private readonly PDO $pdo)
    {
    }

    public function hit(string $key, int $limit, int $windowSeconds): array
    {
        $start = (int) floor(time() / $windowSeconds) * $windowSeconds;
        $startSql = date('Y-m-d H:i:s', $start);

        $stmt = $this->pdo->prepare(
            'INSERT INTO rate_limit_counters (bucket_key, window_start, hits)
             VALUES (:key, :start, 1)
             ON DUPLICATE KEY UPDATE hits = hits + 1'
        );
        $stmt->execute(['key' => $key, 'start' => $startSql]);

        $stmt = $this->pdo->prepare(
            'SELECT hits FROM rate_limit_counters
             WHERE bucket_key = :key AND window_start = :start'
        );
        $stmt->execute(['key' => $key, 'start' => $startSql]);
        $hits = (int) $stmt->fetchColumn();

        return [
            'allowed'     => $hits <= $limit,
            'hits'        => $hits,
            'remaining'   => max(0, $limit - $hits),
            'retry_after' => max(0, ($start + $windowSeconds) - time()),
        ];
    }
}
The table behind it is deliberately boring:
CREATE TABLE rate_limit_counters (
  bucket_key   VARCHAR(191) NOT NULL,
  window_start DATETIME     NOT NULL,
  hits         INT UNSIGNED NOT NULL DEFAULT 0,
  PRIMARY KEY (bucket_key, window_start)
) ENGINE=InnoDB DEFAULT CHARSET=utf8mb4;
I ran this pattern against a scratch database on MariaDB 11.8.6 — not against the production database — with a limit of five attempts per sixty seconds, and the behaviour matched the description: the first five attempts were allowed with the remaining count falling to zero, attempts six through eight were refused, and a different key started again from one. The upsert follows the documented INSERT ... ON DUPLICATE KEY UPDATE behaviour in the MariaDB knowledge base.
Two decisions remain yours. Count only failures: if a successful login also increments the counter, a shared office or a family using one account locks itself out during normal use, and the number you actually care about is the count of wrong guesses. And keep the limiter from becoming an amplifier: if every rejected request also writes to the database, a flood of rejections turns your database into the thing that falls over. That is one argument for keeping the expensive check at the edge and letting the application-level counter handle only the requests that already passed it.
Answering in a way clients can obey
When the limit is reached, the response has to carry the two things a client needs: the status and the wait. The MDN page for 429 describes the same contract from the client side — Retry-After may be included to say how long to wait, and the restriction may be server-wide or per resource.
if (!$result['allowed']) {
    http_response_code(429);
    header('Retry-After: ' . $result['retry_after']);
    header('Content-Type: application/json; charset=utf-8');
    echo json_encode([
        'error'       => 'too_many_requests',
        'retry_after' => $result['retry_after'],
    ]);
    exit;
}
Two things the response should not do. It should not reveal whether the account exists, so a limiter must not give a quieter answer for an address that is not registered. And it should not tell a legitimate user that somebody is trying to guess their password, because that is exactly the information an attacker wants. OWASP makes a related point about lockouts: notifying a user about failed attempts with a wrong password is usually inappropriate, while a correct password followed by a failed second factor is a different situation.
On the client side, the correct behaviour is to read Retry-After and wait, not to retry in a tight loop. A client that ignores it and retries immediately has not been slowed by anything except your capacity to absorb the retries. Backoff with jitter is the usual answer when no explicit wait is given.
One nuance about the ecosystem: some servers advertise quota state through RateLimit-* headers. Those names are still specified in an IETF Internet-Draft (draft-ietf-httpapi-ratelimit-headers), which the datatracker still lists as an Active Internet-Draft with no intended RFC status, and a check of the IANA HTTP field name registry on 22 October 2026 showed no registered entry for them. Retry-After is the part every client already understands, so it is the part worth sending.
What a limiter cannot do
A limiter is one layer, and it is the layer that degrades most politely. OWASP is clear that blocking addresses may stop unsophisticated attacks but should not be the sole or primary defence, and that a mitigation should not rely on a single predictable volume limit; both short burst periods and longer periods deserve consideration, because an attacker with many addresses can keep each one individually low. The same guidance recommends a graduated response, for example requiring an additional factor when a login comes from a new device, an unusual location, or a single address showing large login volume.
So a complete answer also includes slow password hashing, multi-factor authentication, and CAPTCHA used as defence in depth rather than as the front door. Rate limiting makes guessing expensive in time. It does not make guessing impossible, and it will not save a system that treats a weak or reused password as acceptable.
A checklist that fits a small server
- Decide what you protect. Server resources, one account, and an expensive operation are different goals needing different keys.
- Start in dry-run mode. Nginx's
limit_req_dry_runand$limit_req_statusshow what a threshold would have done before it does anything. - Restore the client address first. If a proxy or tunnel sits in front, configure the real-IP module and key on the restored address. A limiter on the wrong address is worse than no limiter.
- Use two keys, not one. A coarse edge limit for traffic volume, a finer application limit for the account.
- Count failures, not successes. And keep the counter out of the request path as far as possible.
- Answer with 429 and Retry-After. Then make sure your own front end handles that status instead of showing a broken page.
- Log rejections. A limiter you cannot see is a limiter you cannot tune — but logs are a write path too, so keep them out of the database you are protecting.
- Keep the measures temporary. A block that never expires is a support queue, and OWASP's guidance is explicit that mitigations should be removable as abuse declines.
What I am still unsure about
A few things remain open questions for me rather than settled rules. There is no universally correct number of attempts per minute; the honest source of that number is the traffic you actually observe, which is one reason dry-run mode exists. I am not settled on how a fixed window's boundary allowance should be treated — whether a doubled limit at the window edge is acceptable depends on the endpoint and on how much a user can be hurt by it. And the interaction between a limiter and the other layers is where I expect to learn the most: MFA step-up triggers, CAPTCHA thresholds, and the point at which a blocked request should simply be dropped rather than answered, as RFC 6585 permits.
What I am confident about is narrower and more useful: the protocol already has the right vocabulary for this, and the common failures are not protocol failures. They are counting the wrong thing, counting it in the wrong place, and counting it against an address the server never actually saw.
Conclusion
Rate limiting on a small server is mostly a decision about identity and placement. Decide whether you count an address or an account, decide whether the rejection happens before or after PHP is involved, and make sure the address you count is the address of the person, not of the proxy in front of them. Then use the contract HTTP already gave you: 429, a short explanation, and Retry-After. That is a design a human can reason about and a client can obey — a higher bar than most defensive code clears.
References
- RFC 6585 — Additional HTTP Status Codes (M. Nottingham, R. Fielding, IETF, April 2012)
- RFC 9110 — HTTP Semantics (R. Fielding, M. Nottingham, J. Reschke, IETF, June 2022), section 10.2.3 for
Retry-After - IANA — HTTP Status Code Registry
- IANA — HTTP Field Name Registry
- nginx — ngx_http_limit_req_module
- nginx — ngx_http_realip_module
- Cloudflare — Restoring original visitor IPs
- Cloudflare — Cloudflare HTTP headers
- Cloudflare — Cloudflare IP addresses
- OWASP — Authentication Cheat Sheet
- OWASP — Credential Stuffing Prevention Cheat Sheet
- MDN — 429 Too Many Requests
- MariaDB Knowledge Base — INSERT ... ON DUPLICATE KEY UPDATE
- IETF Datatracker — draft-ietf-httpapi-ratelimit-headers