WebFinger for a Personal Website — Let a Domain Point to a Profile
WebFinger for a Personal Website — Let a Domain Point to a Profile
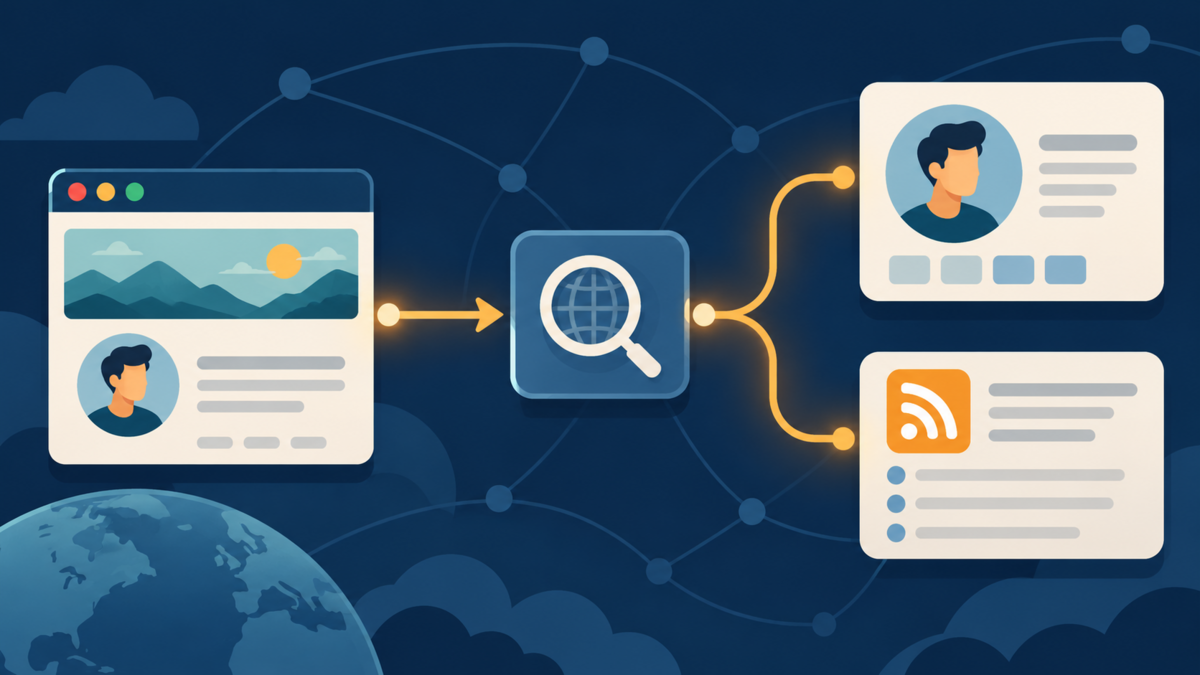
A personal website can have a profile page, an author URL, a feed, and perhaps an account on another service. A human can usually find these links by reading the page. Software does not have that luxury. If someone gives it acct:[email protected], which URL should it request?
WebFinger is one answer to that discovery problem. It gives a client a standard place to ask a domain for information about a URI-identified entity. It is small enough to explain in one article, but it is also easy to misunderstand: WebFinger is a directory-like discovery protocol, not proof that a person controls an identity.
The Problem Is Discovery, Not Login
Humans are comfortable with names that are meaningful but incomplete. “Alice at example.com” is readable, but it does not reveal whether her profile is at /alice, /users/alice, or on a separate host. A client that guesses URL paths is coupled to one site’s internal design.
RFC 7033 defines WebFinger as a way to discover information about people or other entities using standard HTTP methods. The queried thing is represented by a URI. The response is a JSON Resource Descriptor, usually called a JRD, containing fields such as a subject, aliases, properties, and links.
RFC 7033 also notes that the JRD format was originally introduced by RFC 6415. That history is useful, but the WebFinger protocol defines how this descriptor is requested and interpreted for its own applications.
This distinction matters. The client asks, “What links and metadata does this service publish for this identifier?” It does not ask, “Can you cryptographically prove that this person is who they claim to be?” Authentication and authorization need separate mechanisms.
How a WebFinger Request Works
WebFinger uses the well-known path /.well-known/webfinger. RFC 8615 describes /.well-known/ as a reserved path prefix for application-defined metadata locations. RFC 7033 then defines the WebFinger resource beneath that prefix.
A client sends a GET request with a resource query parameter. For an account-style identifier, an illustrative request looks like this:
GET /.well-known/webfinger?resource=acct%3Aalice%40example.com HTTP/1.1
Host: example.com
Accept: application/jrd+json
The percent encoding is not decorative. The value of the query parameter is the URI acct:[email protected], and the colon and at-sign are encoded inside the query string. In a real client, use a URI or query-building library rather than assembling this string by hand.
The host is significant. In the normal case, the query is sent to the host in the target URI. A service can arrange hosted WebFinger infrastructure, but redirects still have to remain on HTTPS and the client must validate certificates. RFC 7033 explicitly says that a failed secure request must not be retried over plain HTTP.
Reading the JRD Response
A minimal response might look like this:
{
  "subject": "acct:[email protected]",
  "aliases": [
    "https://example.com/about/alice"
  ],
  "links": [
    {
      "rel": "profile-page",
      "type": "text/html",
      "href": "https://example.com/about/alice"
    },
    {
      "rel": "author",
      "type": "application/atom+xml",
      "href": "https://example.com/feed.xml"
    }
  ]
}
This is an illustrative response, not a claim about a live endpoint. Its useful parts are the structure:
subjectidentifies the entity described by the JRD. It can be expressed in a canonical form that differs from the requested value.aliaseslists other URI strings that identify the same entity, when the application defines that relationship.linkscontains link relation objects. Arelvalue explains the relationship, whilehrefpoints to a target andtypedescribes its media type.
The meaning of a link is not invented by WebFinger itself. Applications have to define the URI scheme, relation types, and properties they expect. A client should therefore select a link based on semantics it understands, not simply take the first URL in the array.
Why ActivityPub Uses It
ActivityPub gives actors globally dereferenceable identifiers, commonly HTTPS URLs. That is useful once a client knows the actor URL, but a mention such as @[email protected] starts with a handle, not necessarily with the actor’s URL.
ActivityPub itself defines the social protocol and actor representation. WebFinger can serve as the discovery step that maps an account-style handle to an actor URL. Mastodon’s documentation gives a concrete implementation example: it queries the domain’s WebFinger endpoint for an acct: URI, then looks for a link whose relation is self and whose type is an ActivityPub JSON representation.
The two layers should not be conflated. RFC 7033 is application-neutral. An ActivityPub implementation adds its own rules about which JRD link counts as the actor. A personal website can implement WebFinger without becoming an ActivityPub server, just as it can publish an RSS feed without implementing every protocol that can consume RSS.
What a Personal Website Could Publish
A small publishing site might use WebFinger to expose a deliberately limited set of public relationships:
- A profile-page link to the canonical author page.
- An author or feed link to a public feed, if that application is useful to clients.
- An application-specific link only when its semantics and public data policy are clearly defined.
The important word is public. RFC 7033 warns that WebFinger can make personal information easier to discover and says that personal data must not be published through it without explicit authorization. A response does not need to include an email address, phone number, location, or every social profile merely because the format can carry links.
For a custom PHP site, the implementation boundary could be simple: route the well-known path, validate the resource URI, look up only public relationships, emit a JRD with the correct media type, and set a deliberate CORS policy. That is an architectural sketch, not a drop-in implementation. The lookup rules, storage model, cache headers, and error handling still need to be designed for the site.
Security and Operational Boundaries
WebFinger is machine-readable metadata, so it creates a stable discovery surface. The following boundaries are more important than making the endpoint clever:
- Use HTTPS. The protocol requires secure requests and valid certificate handling. Do not silently downgrade when HTTPS fails.
- Control the well-known path. RFC 8615 notes that well-known locations represent the origin broadly. A deployment should prevent an unrelated application or writable directory from taking over the response.
- Scope links carefully. A link in a response is a pointer, not a universal security statement about every related hostname.
- Keep CORS intentional. RFC 7033 discusses browser access and allows broad CORS for public data, but sensitive deployments may need a more restrictive origin policy.
- Rate-limit ordinary abuse. Public discovery endpoints can still receive excessive requests. Caching and sensible limits are operational decisions, not protocol guarantees.
- Do not call discovery authentication. A malicious or compromised server can publish misleading metadata. If a client needs proof of control, it needs a separate verification method.
When Is It Worth Adding?
WebFinger is a good fit when a site has a stable account identifier that external software needs to resolve, or when it participates in a protocol whose application profile expects WebFinger. It is also a reasonable foundation for experimentation with open-web identity, provided the published data is intentionally small.
It is probably unnecessary when a site has no account-style identifiers, no external clients, and no protocol that consumes the result. Adding an endpoint that nobody queries increases surface area without automatically making a website more open. A normal author page with clear HTML links may be the more honest solution.
There is also a maintenance question. A WebFinger response should not point to stale profile URLs, old feeds, or an identity that has silently changed owners. If the site cannot keep those relationships accurate, the machine-readable endpoint may be worse than having no endpoint at all.
Conclusion
WebFinger solves a narrow but real problem: translating a URI-shaped identifier into metadata and links that software can understand. Its endpoint is predictable, its response format is structured, and applications such as ActivityPub show why that separation between a handle and a profile URL is useful.
But the protocol does not create trust by itself. It does not confirm a person’s identity, authorize a client, or turn a personal website into a federated network. For a small site, the sensible path is to begin with the question “who needs to discover what?” and publish only the relationships that have a clear answer.
References
- RFC 7033: WebFinger, IETF, September 2013.
- RFC 8615: Well-Known Uniform Resource Identifiers (URIs), IETF, May 2019.
- RFC 6415: Web Host Metadata, IETF, October 2011.
- ActivityPub, W3C Recommendation, 23 January 2018.
- WebFinger, Mastodon documentation, updated 30 March 2026.